Rohit Sonker
Robotics Ph.D. candidate · Auton Lab, Carnegie Mellon University
I am a Robotics Ph.D. candidate at the Auton Lab, Carnegie Mellon University, advised by Prof. Jeff Schneider.
I build AI agents that make decisions in the physical world: designing experiments, controlling robots and machines, and learning from data that is scarce and expensive to collect. My work brings together reinforcement learning, Bayesian optimization, and large language models, with a focus on methods that hold up outside simulation.
I test these ideas on one of the hardest control problems in science: controlling plasma inside a nuclear fusion reactor. Every experiment is costly, simulators are inaccurate, and the dynamics shift from one run to the next. Methods from my work have run live on the DIII-D tokamak in San Diego.
- AI for scientific discovery. LLM-guided Bayesian optimization that reads expert notes, experiment logs, and domain knowledge to design better experiments with fewer trials. AuxBO (arXiv 2026)·LLM-based BO (NeurIPS WS 2025)·Multi-Timescale BO (ICML 2025)
- Reinforcement learning for real systems. Offline and adaptive RL with learned world models: train from historical data, adapt when the dynamics change, and deploy on real hardware. Adaptive Offline RL (NeurIPS 2026)·RL4F Benchmark (NeurIPS 2026)·Offline RL for Rotation Control (L4DC 2026)
- Robot learning. Dynamics models that infer hidden context on the fly, for robot arms handling changing loads and mobile robots crossing unseen terrain. HiP-RSSM (ICLR 2022)·Terrain-Aware Dynamics (RA-L 2021)
- Multimodal and agentic models. Language and time-series models for reasoning over scientific data, and post-training LLM agents with reinforcement learning and on-policy distillation.
Previously, I spent over four years shipping production ML and LLM systems. I led the India machine learning team at CS DISCO, building LLM agents for legal discovery, and built clinical trial design and document generation systems for pharma clients at PwC. I hold a dual degree (B.Tech and M.Tech) in Mechanical Engineering from IIT Kanpur, where I worked on robot navigation with Prof. Ashish Dutta.
news
| Oct 2026 | Awarded the Indian Institutes of Technology (IIT) Alumni Fellowship for the 2026–2027 academic year. |
| Sep 2026 | New preprint: Bayesian Optimization with Rich Auxiliary Information via LLMs. |
| 2026 | Two papers accepted at NeurIPS 2026: Dynamics-Informed Adaptive Offline RL for Real-Time Tokamak Plasma Control, and Offline Reinforcement Learning for Plasma Control in Nuclear Fusion: Codebase and Benchmark. |
| Jul 2026 | Joined Microsoft Office AI in Redmond as an Applied Sciences Intern, working on RL and distillation for LLM agents. |
| 2026 | Offline Reinforcement Learning for Rotation Profile Control in Tokamaks accepted at L4DC 2026. |
| 2025 | Oral talk at APS-DPP 2025: Dynamics Model Bayesian Optimization for Experimental Design in Tokamaks. |
| 2025 | Multi-Timescale Dynamics Model Bayesian Optimization for Plasma Stabilization in Tokamaks accepted at ICML 2025. |
publications
* equal contribution. Full list on Google Scholar.
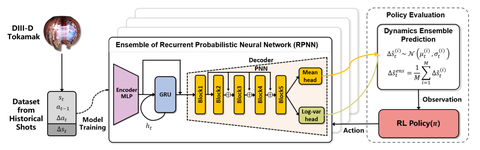
Control policies trained entirely from historical data, using a learned world model of plasma dynamics. The policies infer a hidden context and adapt in real time when the dynamics shift. Validated in experiments on the DIII-D tokamak.
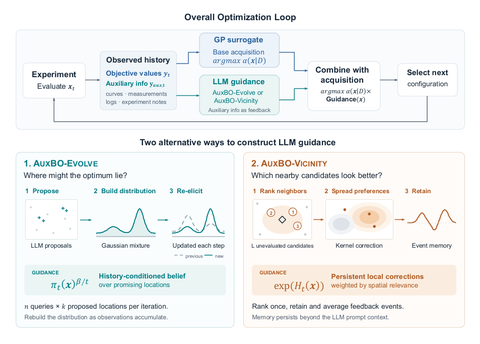
Standard Bayesian optimization keeps only an input and a score from each experiment. We use LLMs to read everything else an experiment produces, such as training curves, expert notes, and scientists' logs, and turn it into guidance on where the optimum lies. This beats standard and LLM-based BO on benchmarks and a fusion task.
RL4F, an open benchmark for offline RL on long-horizon control with many actuators, built from real DIII-D data. It covers four profile-tracking tasks with closed-loop evaluation. Model-based offline RL performs best on most tasks, but no single method wins everywhere.
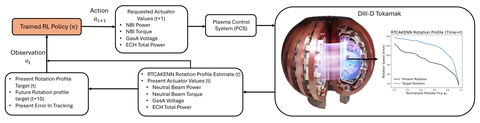
Learning a controller with many inputs and outputs when no accurate simulator exists. Probabilistic dynamics models trained on historical data generate rollouts for RL training. The final policy was deployed on the DIII-D tokamak with promising results.
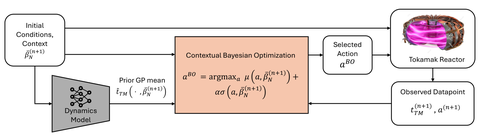
Bayesian optimization that uses a learned dynamics model to make sequential decisions when data is sparse and every evaluation is expensive. Deployed at the DIII-D National Fusion Facility, where it improved instability avoidance by 117%.
An LLM-guided Bayesian optimization framework that draws domain priors from LLMs and folds scientists' natural-language feedback into the choice of the next experiment. This speeds up convergence in experimental design.
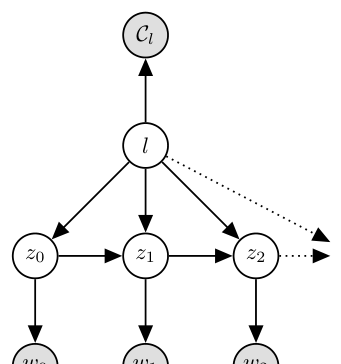
Recurrent state-space models that infer unobserved context on the fly when a system's dynamics change, outperforming meta-learning baselines. Validated by learning inverse dynamics for a Franka Panda robot arm and a pneumatic muscle robot.
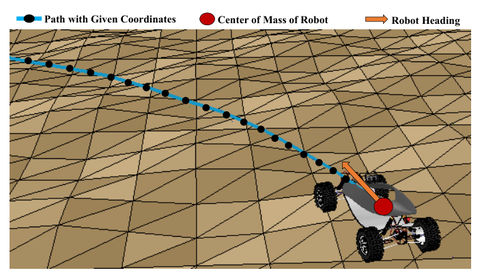
Adding terrain-height context to a learned dynamics model lets a four-wheel robot track paths on uneven terrain it has never seen. The model drives a model predictive controller.
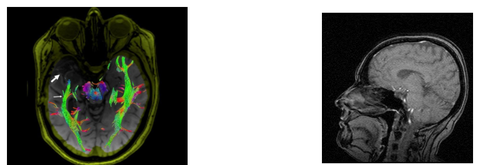
Multi-label prediction of medical concepts from radiology images. Placed 2nd worldwide in the ImageCLEF 2020 medical concept detection challenge.
experience
Auton Lab, advised by Jeff Schneider. Decision-making agents for science and robotics.
On-policy distillation of agentic skills from multiple teachers, and an RL gym for the Outlook agent.
Led the India team building LLM agents for search, summarization, and tagging over legal discovery data.
LLM and ML systems for clinical trial design and regulatory documents in pharma and life sciences.
Robot learning with Gerhard Neumann.
Learned dynamics and model predictive control for mobile robots.
The best way to reach me is by email: rsonker [at] andrew.cmu.edu